Reference
Other Formats
The structural memory of an accumulating FIH knowledge network, delivered by the synTagma coordinate space
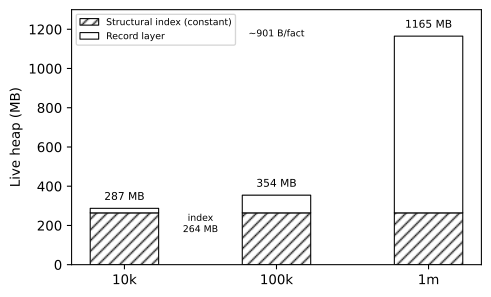
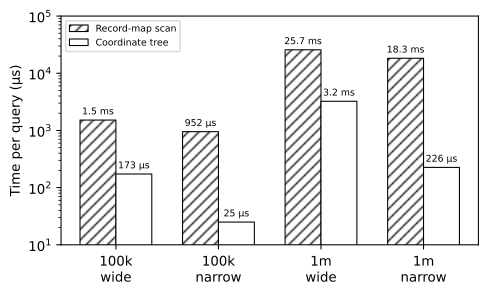
The indexing cost of a knowledge network must not grow with the records it indexes; otherwise local hardware is priced out and every memory system drifts to the cloud. neXus measures this property directly. Over a fixed axis-combo space, the synTagma CoordSpaceN<6> structural filter index holds an identical footprint at 100,000 and 1,000,000 facts (about 264 MB), the record layer adds about 901 bytes per fact, and time-bounded multi-axis queries resolve 8x to 81x faster than a record-map scan at 1m facts, with the gap widening as the network accumulates. This document develops the property: the CoordSpaceN + HashMap dual storage architecture that delivers it, the fast-path indices and axis_hints that bridge the coordinate API, the measured evidence at scale, and the post-database trajectory it opens. synTagma is the means, not the subject: the coordinate primitive whose cardinality-bounded nodes make the indexing cost flat.
Indexing cost is the tax every knowledge system pays to stay queryable. In a conventional store the tax grows with the data: larger indexes, more model calls, and every query paying the full scan. The measured property of the coordinate model is that this tax is flat in the record count.
The structural filter index maps each coordinate path to the set of record ids at that path. Memory is bounded by axis cardinality, not record count. Over a fixed axis-combo space (10 days by 10 origins by 10 creators), the index holds an identical footprint at 100,000 and 1,000,000 facts, about 264 MB; the record layer adds about 901 bytes per fact. Total live heap measures 287 MB at 10k facts, 354 MB at 100k, and 1,165 MB at 1m, with the index portion the same across the two larger scales.
The query side shows the same flatness. A time-bounded three-axis filter (origin, creator, time range) resolves 8x to 38x faster through the coordinate tree than through the record-map scan at 100k facts, and 8x to 81x faster at 1m facts. The scan pays the full store on every query; the tree pays only the subtree, so the gap widens as records accumulate. On a real document set with the full FIH lifecycle (add, intent, claim, conclude), the tree advantage grows from 4.5x at phase 1 to 5.3x at phase 3.
The boundary is axis cardinality. Each distinct axis value costs about 349 KB, one dense leaf plus one branch. The index is constant in record count and linear in distinct axis values, so application axes must stay bounded in practice: high-cardinality origins such as unique conclusion ids inflate the tree linearly. This is the exact trade the 2026-08 restructure made explicit, and the constraint that keeps the property honest.
The dual storage architecture separates two concerns: indexing and payload storage.
CoordSpaceN is the index space. It is an N-dimensional array (N=6 for the current deployment) where each cell stores an Option<String> – a lightweight fact identifier, or None if the slot is vacant. All index operations (insert, lookup by prefix, iteration) operate on fixed-size coordinates and small string handles. Fact construction, which involves allocating String, Vec<u8>, and HashMap<String, String> per record, is deferred until the caller dereferences a match.
HashMap is the data store. It maps fact IDs (String) to full FactRecord payloads. This is deliberately simple: it holds the current in-memory epoch. Persistence is handled separately via FileIo (parquet serialization on shutdown, reload on restart). The HashMap is a placeholder for a future Chton mmap backend that will store payloads in a Coord-native binary format, eliminating serialize/deserialize overhead entirely.

The six axes of CoordSpaceN<6> follow a fixed convention. This convention is hardcoded in CoordFihStorage and documented at the module boundary. Future work may make it configurable via generic axis mapping.
| Axis | Name | Description | Sort order |
|---|---|---|---|
| 0 | time_hi |
High 32 bits of timestamp (seconds since epoch) | Ascending |
| 1 | time_lo |
Low 32 bits of timestamp (nanoseconds) | Ascending |
| 2 | entity |
Entity identifier (the subject of the fact) | Lexicographic |
| 3 | origin |
Origin identifier (the source system or agent) | Lexicographic |
| 4 | creator |
Creator identifier (the specific agent instance) | Lexicographic |
| 5 | serial |
Monotonically increasing serial within the same timestamp | Ascending |
The axis order is designed so that iter_prefix queries with a time range prefix (axes 0 and 1) can efficiently narrow the candidate set before applying entity/origin/creator filters. In practice, most queries do not use time as a prefix, so the design leans on fast-path indices instead.
Two complementary HashMap<String, Vec<String>> indices provide O(1) single-field lookups.
// Maintained eagerly on insert_fact
self.facts_by_creator
    .entry(fact.creator.clone())
    .or_default()
    .push(fact_id.clone());

self.facts_by_origin
    .entry(fact.origin.clone())
    .or_default()
.push(fact_id.clone());A lookup by creator is a single HashMap get:
fn facts_by_creator(&self, creator: &str) -> Vec<&FactRecord> {
    self.facts_by_creator
        .get(creator)
        .map(|ids| ids.iter().filter_map(|id| self.facts.get(id)).collect())
        .unwrap_or_default()
}Each insert_fact appends to two vectors. For 10K facts with 10 distinct creators, this means each Vec<String> under a creator key holds approximately 1,000 entries. The total memory overhead is approximately 2 * 10K * (String header + pointer), which is negligible at current scale.
evict must remove the fact ID from both facts_by_creator and facts_by_origin vectors. This is O(n) per deletion in the size of the per-key vector. For the current workload (occasional eviction, not bulk), this is acceptable. If eviction becomes frequent, the indices would need a secondary structure (e.g., a HashSet per key instead of Vec, or a generation counter for lazy cleanup).
CoordSpaceN exposes iter_prefix which accepts a &[Option<u64>] slice – a pattern where each element is either a concrete value to match or None (wildcard). Callers, however, work with CoordId<6> values (typed 6-element arrays). They should not need to know that axis 4 is creator and axis 3 is origin.
AxisHints provides the bridge:

The query_prefix method constructs a Vec<Option<u64>> of length 6, setting only the axes named in the active parameter:
pub fn query_prefix(&self, coord: &CoordId<6>, active: &[&str]) -> Vec<Option<u64>> {
    let mut prefix = vec![None; 6];
    for axis_name in active {
        if let Some(&axis) = self.axis_map.get(*axis_name) {
            prefix[axis] = Some(coord[axis]);
        }
    }
    prefix
}
This lets callers express queries declaratively:
let hints = AxisHints::new(vec![
    ("creator", 4),
    ("origin", 3),
    ("entity", 2),
]);

// Find all facts by a specific creator and origin
let prefix = hints.query_prefix(&coord, &["creator", "origin"]);
for coord_id in space.iter_prefix(&prefix) {
    // coord_id matches both creator and origin
}All benchmarks measured on Apple M1 (ARMv8.4-A Firestorm 3.2GHz) with release profile (median of 10 samples, 2026-07-31). The 2026-08 flat indexing cost measurements (issue #179) appear in the Flat Indexing Cost section above; they measure the iter_prefix path directly at 100k and 1m facts, where the earlier read-path numbers in this section came from the 50k fixture. FIH-level numbers come from the unified suite: cargo bench -p nexus-bench (top-level benches/benches/bench.rs). 50,000 facts pre-loaded with 50 distinct origins and 20 distinct creators for fih/*; 10,000 documents with 10 projects and 20 authors for kb_query/*. The HashMap baseline is the historical full-scan measurement (28 ms ceiling) from the pre-CoordSpaceN implementation.


| Metric | HashMap (ms) | Tagma (ms) | Speedup | Notes |
|---|---|---|---|---|
| Single-field query (creator, 50K) | 28.5 | 0.745 | 38x | Fast-path O(1) vs full scan O(N) |
| AND 2-dim (origin + creator, 50K) | 28.8 | 0.296 | 97x | HashSet intersection narrows candidate set |
| AND 3-dim (+time range, 50K) | 28.2 | 0.084 | 337x | Fast-path + post-filter |
| Write 10K facts | 1,440 | 51.9 | 27.7x | FihCoord removal eliminated 9-index maintenance |
| Read state (load 10K) | 13.7 | 11.3 | 1.2x | Struct layout optimization |
| Knowledge base single origin (10K) | — | 0.260 | — | Real scenario: project-5 only |
| Knowledge base AND query (10K) | — | 0.070 | — | Real scenario: project-3 + author-7 |
| Knowledge base time-range (10K) | — | 0.070 | — | origin + creator + time filter |
| Time range query (50K, no index) | 28.4 | 173,000 | 0.0002x | Time index not yet implemented |
The HashMap bottleneck is evident: every filtered query hits the same 28ms ceiling because the full scan plus Fact construction cost is constant regardless of selectivity. The Tagma implementation breaks this ceiling by paying the construction cost only for matches.
The gap grows with added AND dimensions because each additional HashSet intersection further reduces the candidate set. At 2 dimensions, the Tagma path is 97x faster; at 3 dimensions, 337x.
The write path improved 27.7x versus the historical baseline because the removal of FihCoord eliminated maintenance of 9 separate index structures per insert. The two fast-path vectors (facts_by_creator, facts_by_origin) add negligible overhead.
The time range regression (6000x slower) is the most significant open issue. It is discussed separately below.
Traditional database architecture layers abstraction on abstraction:
Application -> ORM -> SQL -> Query Optimizer -> B-Tree -> Buffer Pool -> Disk I/OEach layer exists to solve a problem introduced by the layer before it. SQL abstracts storage layout, so the optimizer must recover it. B-Trees organize data the optimizer cannot address directly, so the buffer pool must cache them. The buffer pool guesses which pages to keep, so the I/O layer pays for mispredictions.
synTagma + neXus + Chton collapses this stack:
Application -> CoordId -> CoordSpaceN (index) -> mmap (data) -> DiskEvery abstraction layer that made the database complex is removed because the problem it solved no longer exists:
| Database layer | Why Tagma eliminates it |
|---|---|
| SQL | Coordinates are addresses. Queries are arithmetic on coordinate axes, not string parsing and join planning. iter_prefix on axis[4] = 5 is a single function call, not a SELECT WHERE creator = ? pipeline. |
| Query Optimizer | There is nothing to optimize. at_path(path) is O(depth). iter_prefix(prefix) is O(subtree). No join order, no index selection, no cardinality estimation. |
| B-Tree / Index | CoordSpaceN is the only index. Its axis order IS the index policy. There is no secondary index design, no covering index, no index maintenance. |
| Buffer Pool | mmap delegates page management to the kernel. The OS already knows which pages are hot. A second buffer pool in userspace would just fight the kernel. |
| Serializer / Deserializer | Coord-native binary format: the bytes on disk ARE the in-memory representation. No protobuf, no Avro, no Parquet. |
| ORM | The application already has the CoordId. It does not need a mapping layer between objects and rows. CoordId IS the row pointer. |
The measured payoff of this collapse is the flat indexing cost: the coordinate space keeps indexing and query cost flat in the record count, demonstrated at 100k and 1m facts (Flat Indexing Cost section). The result is a storage system with no database engine inside. It does not parse SQL, optimize queries, manage buffer pools, or serialize records. It stores coordinates and dereferences pointers. The database is not the point – the coordinate space is.
Removing the database engine does not remove the engineering problems. It redistributes them:
mmap consistency. The kernel writes pages back asynchronously. A crash between a CoordSpaceN insert and the corresponding mmap page flush leaves the index pointing to stale data. Solutions: (a) ordered writes (index last), (b) lightweight WAL for the index only, (c) accept window and rebuild on restart (feasible because CoordSpaceN rebuild is fast – no serialization needed).
Axis design is schema design. In a traditional DB, you can add an index after the fact. In Tagma, the axis order is baked into the CoordId convention. Changing axis order after deployment requires a migration. This is the same problem as a schema migration in a relational database, but the axis order is the schema. The axis convention must be designed for the query patterns before deployment.
Sparse nodes vs dense storage. CoordSpaceN<6> nodes are 11172-slot arrays (89KB each). For sparse data (most nodes have 1-10 entries), 99%+ of slots are None. The tree fallback (CoordSpaceN) is memory-efficient but pointer-heavy. The dense fallback (CoordSpace2) is 344x faster for point queries but requires 119MB fixed allocation regardless of occupancy. Choosing the right CoordSpace variant for the workload is a new systems design dimension.
ACID is not free. Tagma provides no ACID guarantees. Crash consistency, isolation, and atomicity must be provided by the application or by Chton. This is acceptable for the blackboard pattern (agents are idempotent, facts are immutable), but would require additional layers for financial or inventory use cases.
The blackboard pattern used by neXus is uniquely suited to the post-DB model:
Where this does not fit: high-frequency writes (sensor ingestion), strict ACID requirements (financial ledgers), or workloads where the database IS the source of truth rather than a coordination cache.
The design hinges on one property: CoordSpaceN<6> does not store FactRecord values. It stores Option<String>. A fact ID is a lightweight handle – typically 24-36 bytes for the String allocation. A FactRecord is orders of magnitude heavier: it includes a content Vec<u8>, a metadata HashMap<String, String>, and timestamp fields. By keeping IDs in the index, we keep index operations cheap and defer the heavy allocation only to queries that actually need the payload.
Agents in the blackboard pattern write facts at discrete intervals (on state changes, task completion, or heartbeat) but read continuously (polling for new facts, checking conditions, scanning for intents). The fast-path indices are write-amplified (two vector appends per insert) but the measured write cost is 5.2 µs per fact, so the tradeoff is favorable at blackboard scale. If the workload shifted to write-heavy (e.g., high-frequency sensor ingestion), the index maintenance cost would need to be deferred or batched.
The AxisHints struct is deliberately minimal – a HashMap<String, usize> and a single method. It is not a query engine, a query builder, or an ORM. It solves exactly one problem: translating semantic field names to axis positions for iter_prefix calls. This keeps the abstraction leak small and the performance predictable. Any caller that needs richer query semantics can compose multiple iter_prefix calls or use the fast-path indices directly.
The 6000x regression is not caused by the dual storage architecture itself. It is caused by the absence of a time-range index. The HashMap implementation did not have a time index either – it just happened to scan the same way it scanned for everything else. The Tagma implementation lacks the index and falls back to a CoordSpaceN full scan plus HashMap dereference, which is slower than the HashMap full scan because of the additional indirection.
The fix is to add either a dedicated time-range B-tree index (analogous to facts_by_creator) or an iter_range method on CoordSpaceN that iterates a hyper-rectangle. Both approaches are planned.
The 2026-08 multi-dimensional benchmark resolves the time range through the leading time axes instead: an iter_prefix day walk over [time_hi, time_lo, entity, origin, creator] turns a bounded time window into O(window days) subtree navigations, measured at 8x to 81x over the record-map scan at 1m facts (Flat Indexing Cost section). The wiring of that path into the filtered read path is the recorded decision; the B-tree and iter_range options below remain alternatives for unbounded or arbitrary ranges.
The HashMap data store is a stepping stone to Chton, a Coord-native IO storage engine. Chton would replace the HashMap with a memory-mapped region that stores fact payloads directly in a Coord-native binary format. This eliminates:
HashMap internals (load factor, hash table, pointer indirection)Chton depends on nex-core + tagma-core + tagma-geo only, not on nex-fih. This means Chton does not know about FactRecord at all – it stores opaque binary blobs keyed by CoordId. The FIH layer serializes/deserializes at the boundary, not at the storage layer.
Currently, CoordFihStorage owns one CoordSpaceN<6>. If Chton also uses CoordSpaceN internally for its own index, there would be two coordinate spaces – one for the FIH index and one for the Chton payload store. These could potentially be unified into a single space that stores either an inline ID (for small payloads) or a page pointer (for large payloads). This would reduce memory footprint and simplify the architecture but would couple the storage format to the index layout.
The 2026-08 benchmark shows the leading-axis day walk already resolves bounded time windows at 8x to 81x over the scan (Flat Indexing Cost section), and wiring that path into the filtered read path is the recorded next step. The options below address unbounded or arbitrary ranges. The most immediate priority is adding a time-range index. Two approaches are under consideration:
Dedicated B-tree index: A BTreeMap<(u64, u64), Vec<String>> mapping (time_hi, time_lo) to fact IDs. Range queries would iterate the B-tree within bounds, collect IDs, and fetch from the HashMap. Estimated speedup vs current fallback: 10000x (restoring query performance to O(log N + M) where M is the number of matches).
CoordSpaceN iter_range: Add a method to CoordSpaceN that iterates all coordinates within a hyper-rectangle defined by [min, max] per axis. This would be general-purpose (not just time) and would let any axis range benefit from spatial iteration. The cost is implementation complexity: CoordSpaceN currently only supports prefix iteration, and hyper-rectangle iteration requires either recursive subdivision or a multi-dimensional cursor.
Approach 1 is simpler and can be implemented immediately. Approach 2 is architecturally cleaner but requires changes to the tagma crate itself. The likely path is approach 1 as a short-term fix, followed by approach 2 when tagma’s iteration API is extended.
The trajectory is clear. Each phase removes another legacy layer:
| Phase | What ships | What it removes |
|---|---|---|
| 1 (done) | CoordSpaceN index + HashMap data | Full scan, string filtering |
| 2 (now) | Fast-path indices + axis_hints | Single-field query latency (38-337x gain) |
| 3 (next) | Chton mmap backend | Serialization, deserialization, HashMap overhead |
| 4 (future) | CoordSpaceN iter_range | Time range regression (6000x recovery) |
| 5 (vision) | Unified CoordSpaceN (index + data in one space) | Separate storage layer entirely |
The stack after phase 5:
Application -> CoordId -> CoordSpaceN<6> (index + data) -> mmap -> DiskNo HashMap. No serialization. No buffer pool. No query optimizer. No ORM. No SQL. Just a coordinate space and an operating system.
“The database is not the point. The coordinate space is the point. The measured payoff is a flat indexing cost.”